

What workflows are
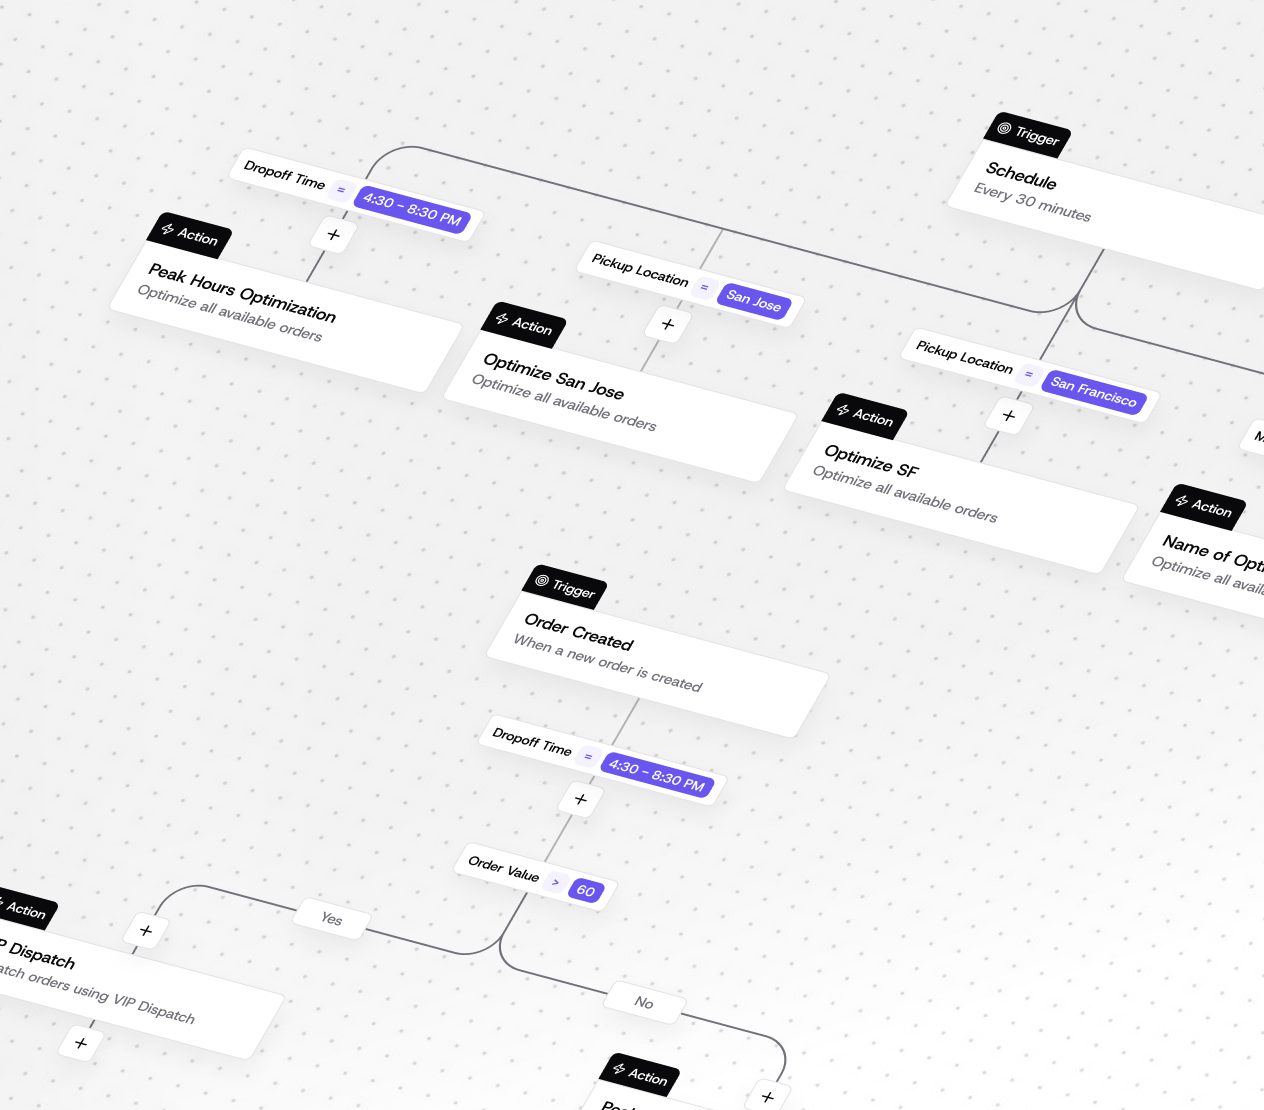
A workflow is built from nodes connected by edges, plus a trigger that defines when it runs.- Nodes are the steps of the workflow. Each node has a type:
trigger— the entry point that starts the workflowfilter— evaluates conditions and branches the flowaction— performs an operationswitch— routes execution based on a value
- Edges connect nodes and define execution order. An edge type of
defaultis used for trigger and action nodes. For filter nodes,successfollows when the condition is met andnegativefollows when it is not. An AI Decision node usesdecisionedges, each carrying abranchKeythat names the outcome it follows. - A trigger defines the event that activates the workflow.
draft, active, inactive, archived, and template. New workflows are created in draft by default and must be set to active to run. Updating a workflow’s structure (nodes, edges, and trigger together) creates a new version.
Actions
Action nodes perform operations on the order or delivery, or send notifications. Supported actions include:- Apply a dispatch strategy or an optimization strategy
- Modify order price or tip — set a value outright, or bound one: At least raises anything under a floor, At most caps anything over a ceiling, and both leave a value already inside the bound alone
- Add a tag or extract a metadata field
- Flag a task or delivery, auto-reassign, cancel a delivery, cancel an order, or remove an order from a route
- Raise, update, resolve, or assign a route flag so a detected condition becomes durable work on the Execute page rather than a notification someone has to catch
- Add requirements to an order
- Update order text while an order is being created — add text before or after the order description or the pickup or dropoff instructions, replace it, or fill it only when it’s missing — see Fill in instructions as an order is created
- Update order metadata while an order is being created — add, update, or remove one metadata key and leave the rest alone — see Change one metadata key
- Reschedule an order that hasn’t been dispatched, moving every pickup and dropoff window by the same amount — see Reschedule an order
- Mark an order invalid from a validation workflow, so a rule of your own parks the order alongside Nash’s built-in checks — see Validate orders with your own rules
- Send a notification by email, SMS, Slack, or Teams channel message
- Summarize, run an agent call or browser automation, or emit a custom event
- Send an HTTP request to a system of your own
- Branch with an AI Decision when the question is a judgment — yes or no, one of your named outcomes, or a score against a rubric
- Hand the step to a Custom Agent and branch on what it reports back
The exact set of actions, their configuration schemas, and the available filter fields and operators are self-describing. Call
GET /v1/workflows/schema to retrieve the current triggers, action config schemas, filter fields and operators, and supported node, edge, and status types.Triggers & conditions
A workflow’s trigger specifies what activates it. Trigger types includeevent, manual, webhook, and cron. Event triggers listen for a named event in Nash — for example order.created or order.creating. (Currently, the REST API for creating workflows supports the event trigger type; other trigger types exist in the platform but are not all exposed through that endpoint.)
A trigger built on a delivery status transition can name several statuses in deliveryStatuses and fires on each of them on its own, so one workflow covers pickup and dropoff without being built twice.
Conditions are expressed with filter nodes. Each filter holds one or more conditions made up of a field, an operator, and a value. When the filter evaluates true, execution follows the success edge; otherwise it follows the negative edge — letting you branch a workflow based on order attributes. The available fields and operators are returned by GET /v1/workflows/schema.
Fire against a pickup or dropoff window
Most triggers react to something that has happened. Four react to a time that is coming.order_pickup_start_time, order_pickup_end_time, order_dropoff_start_time, and order_dropoff_end_time fire against the order’s own window timestamps, offset by however long you choose — “30 minutes before the dropoff window ends”. Each takes a direction of before, at, or after and an offset_minutes.
This is the trigger for the order that hasn’t moved: a pickup due in twenty minutes with no provider on it, a dropoff window about to close on a store that hasn’t packed. Nothing has happened, which is the problem.
If the window moves after the timer is armed, Nash arms a new one against the new time and the superseded timer does nothing when it comes around.
React to a route
A route is a workflow context of its own. Five triggers sit under Routes in the builder: Route Created (route.created), Route Started (route.started), Route Stop Completed (route.stop_completed), Route Completed (route.completed), and Route Canceled (route.canceled). Every one of them carries the route’s own fields:
In the API the keys are
route.id, route.status, route.provider, route.driver, route.stop_sequence, route.stops_completed, route.total_stops, route.planned_departure, route.actual_departure, and route.planned_completion. Delivery, task, and order fields may be present depending on the route, and the field picker marks them as possibly empty.
The route-flag actions are the natural pair. A workflow on Route Started that finds Actual Departure well past Planned Departure can raise a route flag, so the late departure is work on the Execute page with an owner rather than a message someone has to catch — or send a Slack message with {{route.driver}} in it, or call your own system.
Match an event from your catalog
Anevent trigger matches on the event’s name. If your organization keeps a catalog of custom event definitions, point the trigger at a definition instead of typing that name: send customEventDefinitionId on the trigger and Nash stamps the definition’s key as the event name it matches on. The two can’t drift apart afterwards, and a definition something is still listening for can’t be archived out from under the workflow — whether the listener is a workflow trigger or a plain notification.
In the Portal, a Custom Event Listener trigger carries an Event context selector — order, delivery, task, or job — naming the entity the event belongs to. That choice decides which conditions and actions the builder offers downstream, so changing it resets the actions already placed after the trigger.
The same reference works on the writing side. POST /v1/order/{id}/events and its job equivalent accept customEventDefinitionId in place of name, and so does the emit_custom_event action. Send one or the other; sending both is rejected, as is a definition from another organization or one that has been archived.
Branching on whether a field is there
Two operators take no value at all. Is set and Is missing ask whether a field or a metadata key is present, which is a different question from what it contains. Onlynull and genuinely absent values count as missing. 0, an empty string, and an empty list are all set — so a condition asking whether someone filled in a tip doesn’t quietly treat a deliberate zero as a blank. A presence check against context the workflow doesn’t have yet, such as a delivery on an order that hasn’t been dispatched, resolves to missing rather than failing the step.
Fields worth branching on
The field catalog spans the order, its packages, the job (delivery), and the delivery attempt, and it is served live byGET /v1/workflows/schema — the Portal’s workflow editor reads it from there, so new fields appear without a Portal release. Alongside the address, value, tag, and requirement fields, it carries the numbers a routing or escalation decision usually turns on:
Order fields are available on every trigger that has an order behind it, including delivery, job, and delivery-attempt triggers, so a delivery-status workflow can branch on the order’s value or tags. A condition on an order field in one of those contexts used to resolve to nothing; if you built one earlier and it never took the branch you expected, it does now.
In the Portal, the field picker offers only fields whose entity can exist for the trigger you’ve chosen, and marks a field that may be empty for that trigger — a delivery field on an order-created trigger, say — so a condition that can never match isn’t offered as though it could.
Comparing times
Date and time fields carry their own operators rather than being matched as text. A condition can compare a timestamp against a fixed moment, against a relative window — within the last, more than, less than a duration you name — or against another datetime field, which is how you ask whether a dropoff window closes before its pickup window does. Evaluation is time zone aware, and a weekday reads the same regardless of where the person editing the workflow is sitting. A dispatch strategy is a field you can branch on too, so a workflow can ask which strategy an order is already flowing through before it decides to change it.Branching on whether an event has happened
Is set asks whether a field has a value. A different question is whether something has happened to this order — has the store sent itsstore_ready event yet? Four filter-only fields answer it: order.custom_event, job.custom_event, task.custom_event, and delivery.custom_event, each paired with the operators Has occurred and Has not occurred and a value that is the exact key of the custom event you mean. Pick it from your catalog, or type a key by hand to match an archived or legacy one. A workflow on a pickup-window trigger can then continue only when the order has no store_ready event.
The check is taken at the moment the trigger fires and stored with the run, so a worker that picks the run up late, or a retry, can’t see an event that arrived in between and flip the branch. If the entity the condition refers to can’t be resolved, the step errors rather than treating “not found” as “hasn’t happened”. These fields exist only to be filtered on; they don’t hydrate into a message.
Validate orders with your own rules
Nash checks every order it takes in — an address that won’t geocode, a pickup time in the past — and parks an order that fails as needing attention, with the reasons invalidationErrors. Some rules are yours, not Nash’s: an unattended delivery needs dropoff instructions, a reference ID has to match your ERP’s format, a barcode has a fixed shape. A workflow on the Order validation trigger (order.validating) adds those checks to the same pass.
The trigger runs synchronously inside every validation of an order — on creation, on every update, and on CSV upload — and the workflow can hold only filters, switches, and the Mark order invalid action. It runs before any order-created workflow, so a rule can’t depend on a field one of those fills in.
Mark order invalid (add_validation_error in the API) takes a field and a message. The field is a camelCase key of up to 64 characters: use one of the order’s own fields, such as dropoffInstructions, and the Portal’s order form highlights that field, or use a key of your own. A few keys Nash uses itself are reserved. The message can carry {{order.*}} variables. The error lands in validationErrors next to Nash’s own, the order’s status becomes needs_attention, and the key clears on the next update that satisfies the rule. Every run, including one that marked nothing, appears in the workflow’s Runs view.
Two filter operators arrive with it. Matches pattern and Does not match pattern (matches_regex, not_matches_regex) test a string field against a regular expression, matched anywhere in the value — anchor with ^ and $ to check the whole thing. On a list field, matches pattern needs every item to match, and does not match pattern passes when any item fails. Patterns are compiled when you save, so a broken one is refused there rather than at run time.
A validation workflow fails closed. If it can’t run, or one of its conditions can’t be evaluated, the order is marked with a reserved workflowValidation error naming the workflow, rather than slipping through as valid.
Two things this trigger can’t do: it can’t be run by hand, because a validation only makes sense inside an order’s own validation pass, and it can’t carry any action other than Mark order invalid. Nash refuses both when you save or activate the workflow.
Fill in instructions as an order is created
Instructions are the field that most often arrives empty — the ordering system didn’t ask, or the customer left it blank — and an empty one is what the driver reads at the door. A workflow on the Order being created trigger (order.creating) can fill it in before dispatch with the Update order text action (modify_order_instructions in the API).
Pick Pickup instructions, Drop-off instructions, or Order description, then how the text applies: Add before existing text (the default), Add after existing text, or Replace existing text, which overwrites everything there, customer notes and address lines included. Only when instructions are missing treats blank text, N/A, and an address-only line as missing and leaves anything else alone. For the description the equivalent is Only when the description is empty, and only an empty or whitespace-only description counts. Use one action node per field, and the workflow’s filters to limit it to a store or a delivery model.
The action writes the order, and any package location already built from it, so what dispatch sends carries the text. Combined text longer than 280 characters fails the step rather than being cut — the description included — and a pickup override from a provider or store keeps precedence. It runs after order validation: if a validation rule of yours rejects orders with no instructions, adjust it when the intent is to fill them in instead.
Change one metadata key
The same trigger can write order metadata. Update order metadata (modify_order_metadata in the API) changes one key per node and leaves every other key as it was:
The value is text, a number, a boolean, or null. A value that is one whole
{{variable}} keeps the type it had where it came from, so a barcode with leading zeroes stays a string rather than becoming a number.
Name the key exactly. Variables and wildcards aren’t accepted in the key, a node can’t clear all metadata at once, and keys Nash manages itself — anything beginning with nash, among a few others — are refused. The change is written to the order and to the package record already built from it, so a later sync doesn’t undo it.
Both actions belong to the Order being created trigger only. Nash refuses them on any other trigger when you save or activate the workflow.
Reschedule an order
A store closes early, a truck is a day late, a customer asks for tomorrow: the order’s pickup and dropoff windows all need to move, together. The Reschedule order action (reschedule_order in the API) does that from a workflow, on any order trigger other than the two that run while an order is being created or validated.
Choose a Reschedule method:
- Delay moves the order later by a duration — whole minutes, from 1 minute to 365 days. The Portal takes minutes, hours, or days, offers 12-, 24-, and 48-hour presets, and starts at 24 hours.
- Move to date takes a calendar date (
YYYY-MM-DD) and keeps the local clock time. An order whose pickup window opens at 9:00 opens at 9:00 on the new date.
- It’s a scheduled order, with at least one pickup or dropoff time.
- It hasn’t been dispatched or archived — its status is
valid,confirmed, orneeds_attention. - It isn’t on a route. Remove it from the route first.
- It has no booked delivery window. Change the booking instead.
- Every resulting time is in the future, and the rescheduled order still passes validation.
Writing text with variables
Any text a workflow sends — an email subject, an SMS body, a Slack message, the channel it goes to — can carry{{variables}} that Nash fills in when the run reaches that step.
Filters produce results too. A filter node publishes
__result ("true" or "false", absent when the filter couldn’t be evaluated) and __status (completed or error), so a message or an AI Decision further down can say which way an earlier condition went.
Every notification action — email, SMS, Slack, Teams, and voice-agent calls — reads the same catalog the notification triggers use, so a message you write in a workflow and a message you write in Notifications have the same vocabulary. The catalog hydrates the destination and the subject as well as the body: a Teams channel or an SMS recipient can be a variable instead of a hard-coded address.
A variable that can’t resolve at the node you’re editing is refused when you save, with the nearest match suggested, so a typo surfaces before the workflow runs rather than as a blank in a message. At run time a variable that resolves to nothing hydrates to empty text. On message actions a key that doesn’t exist at all fails the step; the Send HTTP request action is more forgiving, and sends anyway — see Call your own system.
A Send email action takes several addresses, comma-separated. Each is checked against the deny list and delivered on its own, so one refused or bouncing address doesn’t take the rest with it. In the Portal, Fill addresses from destination copies the current addresses of one of your notification destinations into the field. It’s a one-time copy: a later change to the destination doesn’t follow.
In the Portal’s editor, destination fields suggest only variables that could plausibly address that channel: phone numbers for SMS and voice, addresses for email, channels for Slack. The message body itself stays unrestricted.
Call your own system
Everything above acts on Nash. Sometimes the next step in your process lives somewhere else — mark the order picked in your WMS, open a ticket, tell your ERP the delivery failed. The Send HTTP request action makes that call from inside the workflow, so the handoff happens where the decision was made rather than in a listener you have to run and monitor yourself. It works in two halves, deliberately:- An administrator creates a connection. The connection owns the HTTPS origin, the credentials, which methods are allowed, the path prefix requests must sit under, and the names of the request fields a workflow may set. Credentials are write-only: they never appear in the workflow definition, and they are kept out of request logs and error reporting.
- A workflow author references it. On the action node you set a relative path, query parameters, headers, a JSON body, a timeout, and what the workflow does if the call fails. Templates work here the same as anywhere else, so the body can carry the order’s own values.
null for a whole value, and the request goes out, with each miss recorded on the run’s step so a request that left with an empty field is still explainable. When the call does fail, the step says at which stage — building the request, connecting, authenticating, transport, the HTTP status, or reading the response — so a request that was never sent isn’t reported as one that failed.
The action runs in the background and makes one attempt, carrying a stable idempotency key so your endpoint can recognize a repeat. It is not a durable delivery channel: treat it as a signal your system can act on, not as a queue that guarantees arrival. It also can’t hold up a synchronous run.
Running a workflow by hand
Triggers cover the routine cases. Sometimes you need to run one yourself — to apply a workflow to orders that predate it, or to check a change before you turn it on. Start a workflow on demand with the Trigger Workflow endpoint (POST /v1/workflows/{id}/trigger), passing entity references (such as the ID of a job, i.e. a delivery) and optional input data, in synchronous or asynchronous mode.
A manual run works on a workflow in either active or inactive status. That’s the useful part of inactive: a workflow you’ve switched off no longer fires on its own, but you can still run it deliberately. Workflows in draft, archived, or template status are rejected.
In the Portal, select the orders you want on the Orders page and choose Run Workflow from the action bar. Pick the workflow, add trigger input if it needs any, and Nash starts one run per selected order — each independent, each with its own result you can open. Selecting orders row by row is what’s supported here; a workflow run needs a concrete order to reference, so “select all results” across pages isn’t.
Run history
Every run of a workflow, whether a trigger fired it, you ran it by hand, or a script started it through the API, is recorded as an execution with one step per node the run reached. Use it to answer “did the workflow fire for this order, and what did it do?” without adding logging of your own. In the Portal, open a workflow and switch from Editor to Runs; the toggle itself shows the most recent run’s status and how long ago it was. A strip above the builder keeps four numbers in view — Runs today, Success rate, Errored, and Avg run time — and each person can hide it. Each row in Runs shows the run, the orders or deliveries it was about, when it completed, how long it ran, and its status. Open a run to see when it was created and completed, its total runtime, and the steps it took, each with the node it ran, that step’s status, and when it started. The same history is available through the API:GET /v1/workflows/{id}/executionslists a workflow’s runs. Filter bystatus,startDate,endDate, orsearch; order withsortByandsortDirection; page withlimitandoffset.GET /v1/workflows/{id}/executions/countreturns how many runs match the same filters.GET /v1/workflow-executions/{id}returns one run with its steps.
id, status, createdAt (when the trigger fired and the run was created), completedAt, runtimeSeconds (the difference between the two), and the orderIds, jobIds, and deliveryIds it was about. Each step carries id, nodeId, status, createdAt (when the step started), and nodeVariables, the data the run had in hand when it processed that node, including what earlier nodes produced.
pending, queued, running, completed, failed, cancelled, and paused. Step statuses say what a filter decided as well as whether an action ran: completed_filter_success and completed_filter_negative are the two branches of a filter, completed_filter_error is a filter that couldn’t be evaluated, completed and failed are the outcomes of an action, and paused and ready_to_resume appear on a step while the run is waiting to continue.
Two limits worth knowing before you build on it. A step records when it started, not when it finished, so per-step durations aren’t available; the run’s runtimeSeconds covers the whole run. And retries aren’t recorded: a step shows its final outcome, not how many attempts it took.
Test a workflow before you activate it
Running a workflow tells you what it does. Testing one tells you what it would do, which is what you want while you’re still writing it. The alternative is activating a workflow against live orders to find out whether a filter matches. Test a saved workflow withPOST /v1/workflows/{id}/test, passing the jobId or orderId of the entity to evaluate it against. The response reports per-node status, so you can see which filters passed and which branch execution took.
Even a live test can’t change state. Actions like
cancel_order or add_tag are preview-only in both modes, so testing against a real order can’t cancel or modify it. A live test does two real things: it delivers messages, and it evaluates AI Decisions. Use it to check that a Slack or email action is addressed and worded the way you meant, and that a decision lands on the branch you expected.Branch with an AI Decision
Some conditions are a judgment rather than a comparison. Does this delivery note describe a safety problem? Which of four teams should own this failure? How complete is this address? A filter can’t ask that, and an agent is more than the question needs. An AI Decision node (ai_decision in the API) puts one bounded question to a model and sends the run down a branch per outcome.
Give it two things. Question or instructions is what the decision should determine, up to 8,000 characters. Information to evaluate is the context the answer should rest on, up to 32,000 characters — and only what you put there is sent for evaluation. Both take variables, including what upstream actions and filters produced.
Then pick a Decision type:
Every type has two more branches. Uncertain is where an answer goes when the model wasn’t sure enough: between the two thresholds for yes / no, or under the Minimum confidence (0.7 by default) for an outcome or a score. Error is where the run goes when the decision couldn’t be made — a variable in the question resolved to nothing, the expanded text was too large, or the evaluation failed or ran out of time.
Connect Error. Without a step on it, a failed evaluation fails the run. Any other outcome you leave unconnected ends that path quietly. And read confidence for what it is: how sure the model was, not a measured accuracy. Uncertain is the branch a person should look at.
__branch, __status (completed, uncertain, error, or preview), __value, __probability, and __confidence, written as {{node_var_<node key>__branch}} and so on. A downstream filter can compare the confidence, and a Slack message can say which way the decision went.
In the API, edges leaving the node use edgeType: "decision" with a branchKey: yes or no, one of your choices[].key values, above or below, or uncertain or error. A branch takes at most one edge. GET /v1/workflows/schema returns the full config schema for all three decision types.
What it can’t do:
- It can’t sit on a synchronous run. A workflow on Order being created or Order validation would hold the order while the model answers, so Nash refuses the node there when you save, when you activate, and again at run time.
- It can’t read ahead. The question and the context can reference the trigger, the entity’s fields, and upstream nodes only. A reference to the node itself or to a later one is refused when you save.
- It doesn’t investigate. It reads what you hand it and answers. When a step needs to look things up, call tools, or write a report, hand it to an agent instead.
preview status. Turn on Evaluate with the model in the Portal’s Test drawer, or send live: true, to see a real answer. If a step is retried with the same question and context, the earlier decision is reused rather than asked again.
Hand a step to an agent
Filters and actions cover the decisions you can write down in advance. Some steps aren’t like that — read the notes on this order and decide whether anyone needs to be called, look at what the provider has done so far and judge whether the delivery is still recoverable. An agent node hands that step to one of your custom agents and lets the rest of the graph branch on what comes back. The agent receives the entity the workflow was triggered on, the trigger’s own metadata, and the output of every node upstream of it. It does the work — pulls the data it needs, calls the tools it’s allowed to use — and returns a written report, plus the structured fields that go with it if you’ve given the agent an output format. In the API it’s theinvoke_agent action; in the Portal’s workflow editor it’s Run Custom Agent. Either way you pick the agent, write the task context for this particular step, and choose what the workflow branches on.
Branching on what it reports
The node writes its result into the workflow’s variables in two shapes:
The typed per-field variables are the ones worth branching on: a number can be compared, a boolean tested, an enum matched, the same as any other filter field. The full report is the fallback for an agent with no output format — useful to carry into a notification, less useful to filter on.
What an agent node can’t do
- It can’t take actions. Only report-only agents can be selected. An agent that acts would put its actions behind its own confirmation gate, and the workflow would carry on as though they had happened.
- It can’t sit on a synchronous run. Workflows that run synchronously while an order is being created reject agent nodes, because the order would wait on the agent. Nash refuses the combination when you save the workflow, and again if a run attempts it.
- It can’t run unbounded. Each node carries its own timeout and a choice of what the workflow does when the agent fails or runs out of time.
How workflows relate to dispatch strategies
Workflows and dispatch strategies are complementary:- A dispatch strategy answers “given this job, which provider should fulfill it?” — it defines the eligible providers, selection rule, and failover behavior.
- A workflow answers “given this event and these conditions, what should happen?” — including which dispatch strategy to apply.
dispatch_strategy action nodes that apply the right strategy to each branch. This is the same role served by Automations, which map account-level business rules to dispatch strategies; workflows generalize that idea to a broader set of triggers, conditions, and actions.
Next steps
Dispatch strategies
How Nash selects a provider for each delivery.
Automations
Map business rules to dispatch strategies.
Notifications
Configure delivery notifications to customers and systems.
How Nash works
See where workflows fit in the delivery lifecycle.